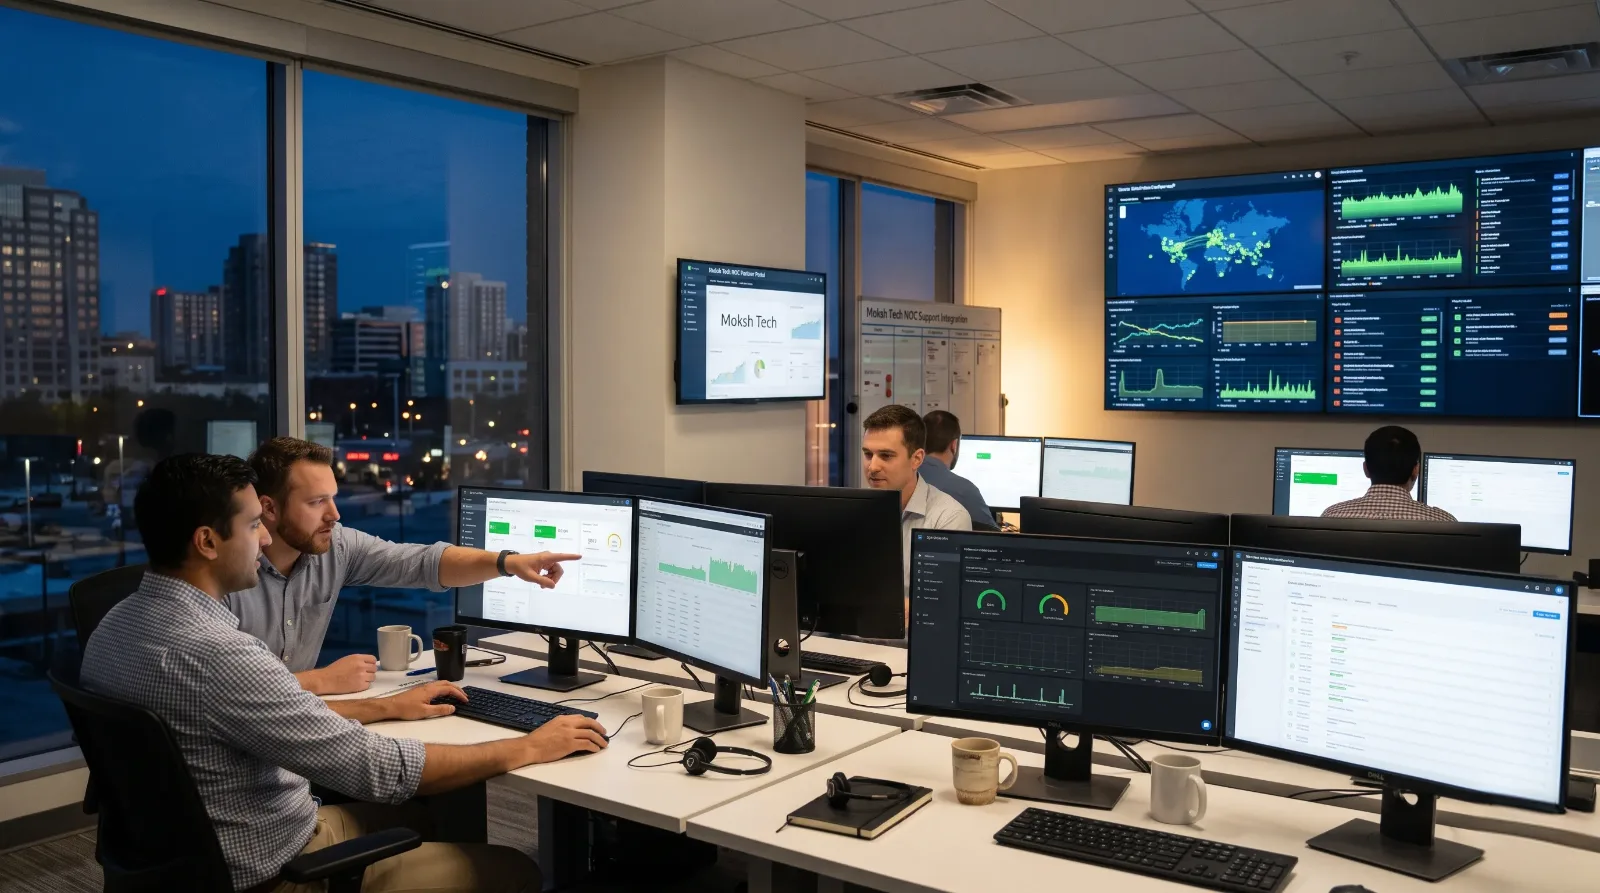
The client is a U.S.-based Managed Service Provider (MSP) supporting approximately 450 endpoints across 25 small and midsize business clients.
Its internal engineering team manages infrastructure monitoring, incident resolution, technical support, and project delivery. However, monitoring operations are primarily staffed during weekdays, leaving overnight incidents dependent on an internal on-call rotation.
As the MSP expanded its client base, maintaining continuous monitoring and consistent incident ownership became increasingly challenging. The business needed a scalable operating model that extended coverage without increasing pressure on its internal engineering team.
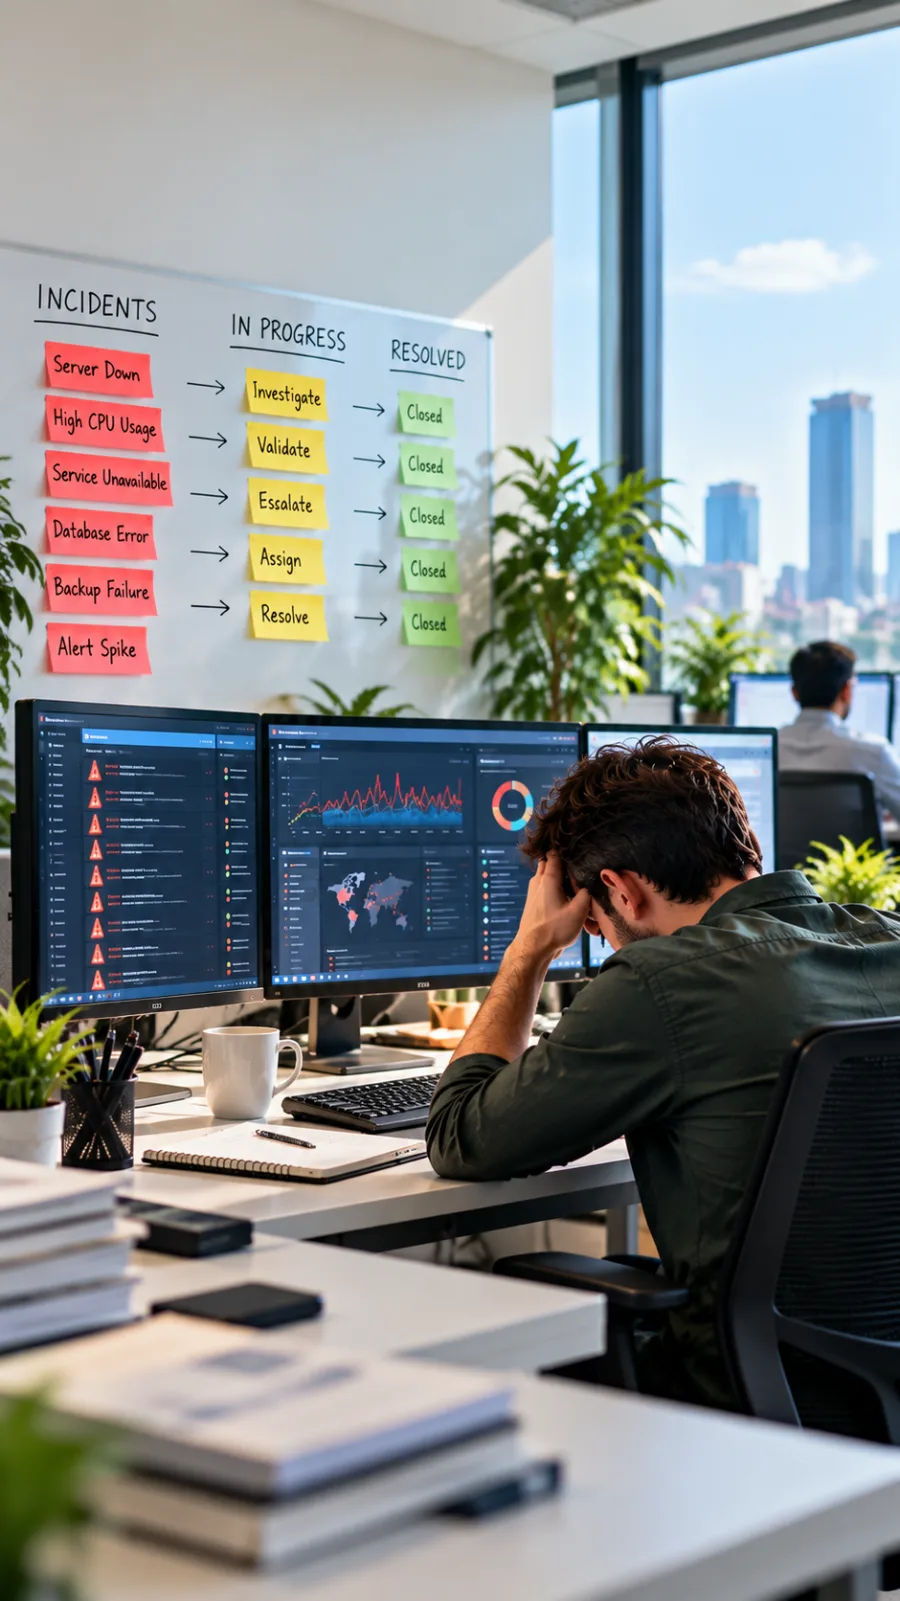
Overnight alerts lacked consistent monitoring and timely review.
Critical incidents depended on the availability of on-call engineers.
Repeated notifications made actionable incidents harder to identify.
Troubleshooting notes and incident details were spread across systems.
Senior engineers balanced overnight incidents with planned projects.
Additional clients increased monitoring demands on the internal team.
Established rostered monitoring across weekdays, nights, and weekends, with planned shift coverage and relief capacity to maintain continuous operational oversight.
Reviewed incoming alerts, correlated duplicate notifications, and prioritized incidents according to severity, affected clients, and infrastructure dependencies.
Created and updated incidents in the existing PSA system, maintaining clear ownership, timestamped records, and documented next actions.
Established P1 paging workflows, a five-minute backup-contact rule, and regular client updates during active critical incidents.
Standardized approved, low-risk recovery actions while escalating unfamiliar failures, suspected security incidents, and actions outside delegated authority.
Recorded open incidents, pending actions, breached timers, and blocked work to maintain continuity between shifts.
Retained the MSP's existing RMM and PSA platforms as systems of record, supported by technical documentation, controlled access, and session logging.
Reviewed recurring alerts, failed automations, escalation delays, response times, and restoration trends to identify opportunities for operational improvement.
| Metric | Before | After |
|---|---|---|
| Staffed monitoring coverage | 40 hours/week | 168 hours/week |
| P1 human-response p90 | 42 minutes | 15 minutes |
| P1 response within 15 minutes | 72% | 95% |
| Mean P1 restoration time | 5.6 hours | Under 4 hours |
| Internal after-hours effort | 64 hours/month | 32 hours/month |
| Critical service availability | 99.70% | 99.90% |
Maintained a defined monitoring presence across nights and weekends, reducing reliance on an internal on-call rotation for routine alert handling.
Moved routine alert validation and approved first-response activities into a structured NOC workflow, allowing internal engineers to focus on complex incidents and planned projects.
Established documented escalation paths, assigned responsibilities, and structured shift handovers for improved operational visibility.
Enabled consistent tracking of incident response, restoration times, recurring issues, and critical service availability.
Established a repeatable support model to help manage growing client demand without relying exclusively on additional internal hires.
Expanded staffed monitoring from 40 to 168 hours per week.
Increased the share of Priority 1 incidents receiving a human response within 15 minutes from 72% to 95%.
Reduced internal after-hours workload from 64 to 32 hours per month.
Reduced mean restoration time from 5.6 hours to under four hours.
Increased measured availability from 99.70% to 99.90%.
“Extending our monitoring coverage has helped us establish a more structured approach to after-hours operations. Clear escalation procedures, consistent incident documentation, and defined ownership have made it easier for our internal team to manage critical issues while maintaining focus on planned work.”
24/7 NOC support provides continuous monitoring of client infrastructure, alert validation, incident documentation, and escalation to designated technical teams. It helps MSPs maintain monitoring coverage outside normal business hours.
White-label NOC support enables MSPs to extend operational capacity while retaining ownership of client relationships and service delivery. The support team works within agreed workflows, communication standards, and escalation procedures.
Yes. NOC operations can use an MSP’s existing RMM, PSA, monitoring, and documentation platforms, provided the required integrations, permissions, and licensing are supported.
Depending on the agreed scope, a NOC team can validate alerts, prioritize incidents, update tickets, perform approved recovery actions, document troubleshooting, and escalate issues to the MSP’s engineering team.
A rostered NOC team handles agreed monitoring and first-response activities across shifts. This reduces the need for internal engineers to personally review routine overnight alerts while ensuring critical incidents follow established escalation procedures.
Response times depend on the MSP’s severity definitions and service commitments. A 15-minute human-response objective can help establish expectations, provided the clock starts at the agreed intake timestamp and automated acknowledgments are excluded.
NOC response time measures the interval between incident intake and meaningful human acknowledgment with ownership. Mean time to restore service (MTTR) measures the interval between the first recorded service impact and verified restoration.
MSPs should track staffed monitoring hours, P1 response compliance, response-time percentiles, mean restoration time, after-hours effort, recurring incidents, and service availability. Measurements should use consistent definitions, periods, and incident cohorts.
No. Continuous monitoring improves the opportunity to identify and respond to incidents, but availability also depends on infrastructure resilience, redundancy, backup integrity, vendor dependencies, and authorized recovery procedures.
An MSP should evaluate coverage schedules, service scope, escalation procedures, L1/L2/L3 responsibilities, tool compatibility, access controls, documentation standards, reporting methods, and total operating costs.
Continuous monitoring requires more than alerts. It requires defined ownership, consistent workflows, documented escalation procedures, and operational accountability.
Moksh Tech helps MSPs strengthen service delivery through 24/7 NOC services and Managed IT Support Services in the USA.
Explore how the right support model can help your team improve monitoring coverage, streamline incident management, and manage growing client requirements.